Specialised AI: measuring the cost of the right decision
TokenShift Executive Note
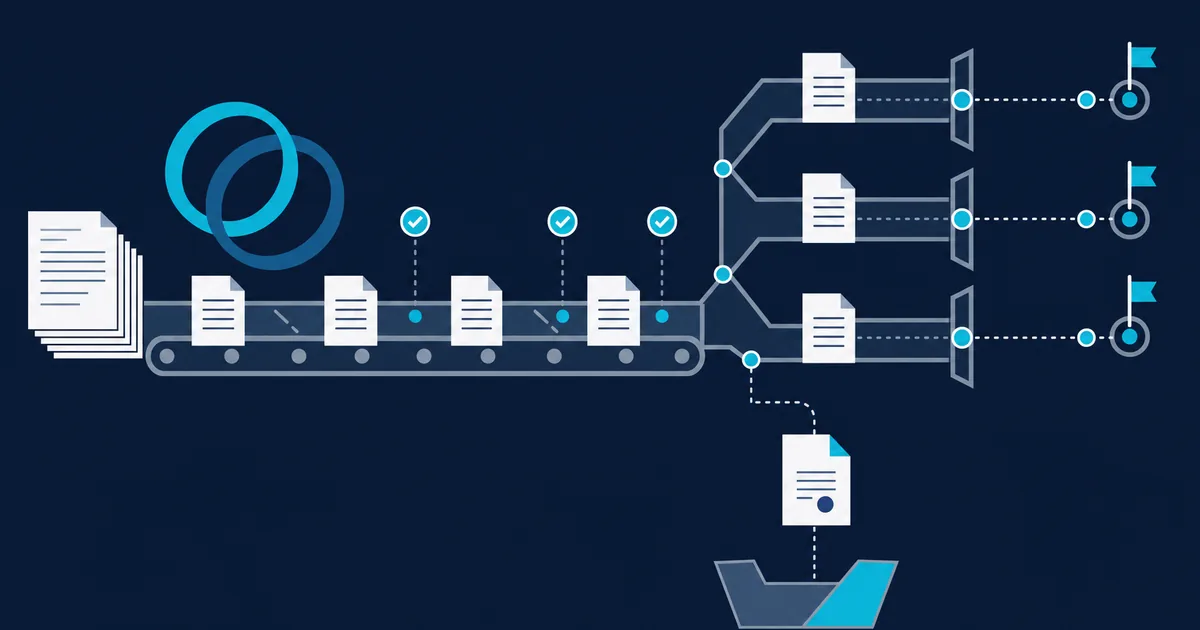
To route a complaint to the right department, a company does not necessarily need AI capable of writing the response. It needs reliable classification, handling for ambiguous cases and an accountable person who can correct errors. Jev and ProgramAsWeights offer two approaches to this specialisation. For an executive committee, their value depends on the cost of a correctly handled case, including corrections.
Two approaches to defining the work assigned to AI
On 15 September 2026, TypeSafe AI announced early access to Jev. The model produces structured decisions with probabilities, rather than free text. The company publishes evaluations across four processes, using other models’ answers as the reference. These results describe performance under this test protocol; they do not demonstrate Jev’s reliability on your company’s cases. TypeSafe AI, September 2026.
The output format does not guarantee that the classification is correct either. A response may belong to the authorised list and still be wrong. TypeSafe therefore documents nine categories of limitations for Jev 1.13, including calculation, date comparison and content designed to influence the model. TypeSafe AI, documentation revised on 17 September 2026.
ProgramAsWeights explores another route: turning the description of a function into a reusable neural program. The research paper, submitted on 2 July 2026, distinguishes preparing that function from its repeated execution, which can then take place locally. These research results still need to be tested in each business context. Program-as-Weights team, 2026.
The architectural choices therefore differ. Jev offers a decision service. ProgramAsWeights enables local execution after preparing and downloading the necessary components, but its documentation also provides for optional remote execution. The selected mode must be examined before concluding that data remains within the company. ProgramAsWeights, documentation consulted in September 2026.
Even locally, maintenance, access, component provenance and updates still need to be managed. Their cost belongs in the comparison.
We draw a common direction from this work: assign AI a precisely defined operation within a wider process. Identifying the reason for a message or proposing where it should be routed then becomes a function that can be evaluated separately.
Including corrections in the cost per case
A cheaper response may lead to more rework. Faster classification may shift the queue to teams handling exceptions. We therefore propose comparing solutions with equivalent scope and quality levels, using this unit:
Cost per correctly handled case = (operating, control and correction costs + amortised share of deployment) / number of cases meeting business criteria.
The denominator requires as much attention as the costs. The absence of an immediate complaint does not prove that a case was handled correctly: some errors may remain silent. Sampling controls, strengthened for sensitive categories, make it possible to look for them.
The finance director must also distinguish released hours from realised savings. Available capacity may absorb an increase in activity without reducing costs. The investment case must specify the intended benefit and how it will be observed.
Defining the decision, including its exceptions
“Route incoming messages to a team” provides a testable scope. “Manage customer relationships” specifies neither the decisions assigned to the system nor their consequences. Describe the task with a verb, an object and a list of authorised outcomes, including an “under review” outcome when information is insufficient.
Assign exact calculations and explicit rules to conventional software. Evaluate AI on the language interpretation that remains necessary.
Let us take a fictional example. An insurance company’s operations director wants to reduce successive transfers between teams. The proposed system is limited to routing messages; compensation decisions remain outside its scope.
A policyholder might write: “I dispute the rejection received yesterday, but I also want to change my address.” A single classification under “policy management” could delay the dispute. The team therefore plans to detect multiple reasons and to take back the case when a combination requires an assessment. The test will need to verify this rule across varied wording. The expected gain remains a hypothesis.
A high confidence score is not enough to authorise an action. Its relationship with observed errors must be verified using the company’s cases. The selected threshold depends on the consequences of a wrong decision and the possibility of correcting it.
The business owner sets the authorised actions and exceptions to be taken back. IT governs access, versions and service shutdown. Compliance examines the intended use and applicable requirements. A classification proposal must not trigger, through software chaining alone, a commitment to the customer: the model’s recommendation and the authorisation to act must be documented separately.
Evaluating the process through to the right team
Operations build a reference sample comprising routine cases, ambiguous wording, missing documents and rare cases where an error would be costly. Disagreements between experts must be resolved before assessing the model.
Separate the cases used to refine instructions from those reserved for final evaluation. Compare the current process, a rules-based solution and specialised AI against the same criteria. An overall average must not conceal errors in a sensitive category.
In the insurer example, monitoring could cover the following indicators:
| Indicator | What it makes possible to verify | | --- | --- | | Sensitive complaints routed incorrectly | The severity of errors behind the overall rate | | Time to reach the right team | The actual delay in the process | | Share of cases taken back manually | The workload transferred to employees | | Cost per correctly handled case | The economic value after control and correction | | Decisions with an exploitable record | The ability to analyse an incident |
If transfers decrease but rework absorbs the time saved, the director has grounds to review the system.
Start by operating the system without changing case handling. Compare its proposals with validated decisions, then progressively authorise the intended actions. Record the version used, the result obtained and human corrections, in accordance with the retention rules adopted.
Set suspension criteria before launch: an increase in critical errors, an accumulation of exceptions or the inability to reconstruct a decision. Test the return to the previous operating model. Any change to the model or instructions must go through evaluation again.
Making expansion conditional on observed results
To decide, the executive committee needs a documented comparison on one process: the decision concerned, a named owner, results on cases reserved for testing, full cost and stopping conditions.
The cited publications justify a targeted trial. They provide neither the economic evidence nor the validation required for your regulated environment.
Authorise expansion when the measurements show a benefit at the required quality level, with a manageable exception workload. Otherwise, reduce the scope or retain the existing operating model.